
Smart Statistics · Reporting insight
Small Sample Sizes in Business Dashboards: When Percentages Mislead
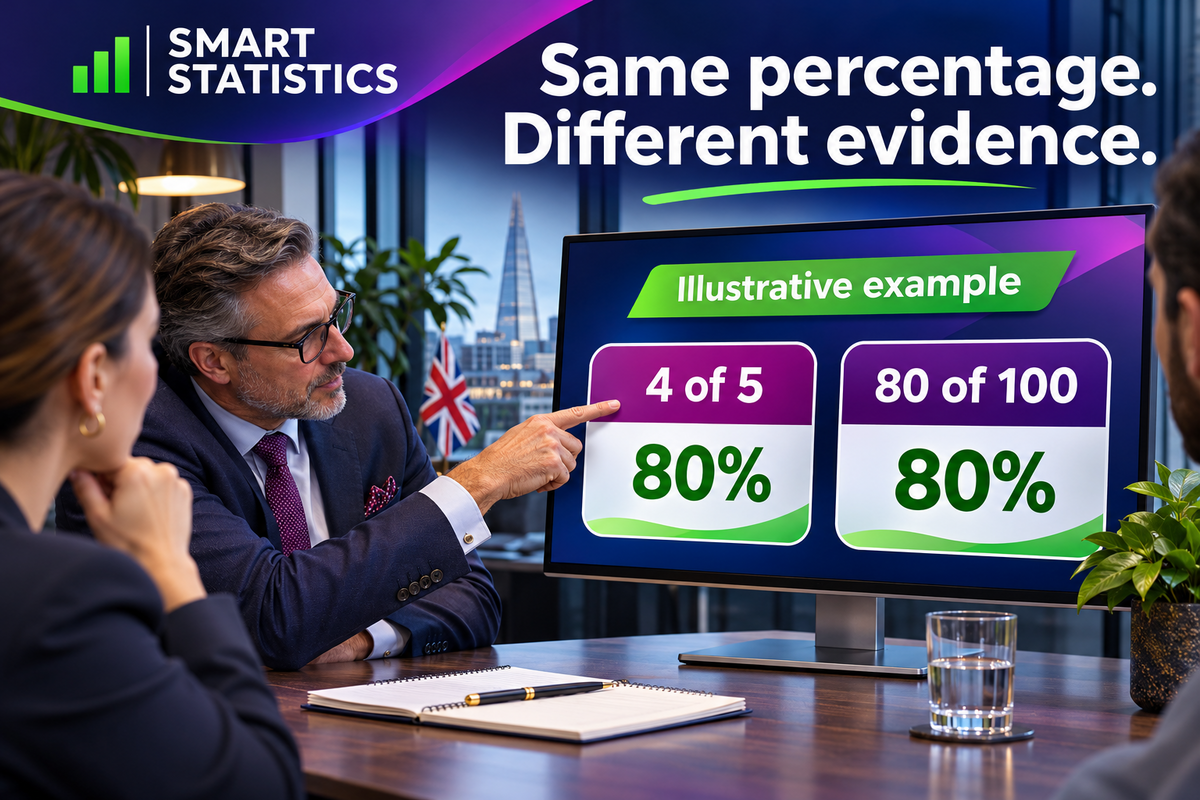
A branch with four positive customer responses out of five shows 80%. Another with 80 out of 100 also shows 80%. The arithmetic agrees; the amount of evidence does not. A dashboard that hides the counts invites managers to treat both results as equally dependable.
For UK businesses comparing branches, service teams or customer channels, the practical question is not simply whether a percentage is correct. It is whether the evidence supports the decision being made from it. Start with customer feedback, then apply the same discipline to conversion and quality reporting.
Illustrative example · Customer feedback review
Identical percentages, very different sensitivity
Illustrative example · Fixed denominators; one positive becomes negative.
Sources: response records and invitation register. Workflow: validate responses → show the base → assess coverage → decide whether to compare. These bars show sensitivity, not confidence intervals.
The meeting that a league table gets wrong
Imagine a service director rewarding the highest-scoring branch each month. A small branch reaches 100% from two replies and rises above a busy branch with a lower percentage from many more customers. The chart has answered “what proportion of respondents were positive?” It has not established which branch delivers the better service.
Respondents may be self-selecting. Teams may invite different customers. One customer may submit several answers. A short reporting window can magnify all three problems. More decimal places add apparent precision without addressing any of them.
ONS guidance explains sampling uncertainty and confidence intervals for survey estimates. Larger suitable samples generally improve precision, but sampling uncertainty is only one source of error. Use that distinction when interpreting business surveys; do not copy a survey interval onto every operational metric without reviewing its design. [1]
Write a decision rule before choosing a colour
The reporting owner should approve a short policy alongside the metric definition. Use the following decision table in a review meeting. These are proposed reporting treatments, not statistical certification.
| Evidence condition | Display | Management action |
|---|---|---|
| No valid responses | “No responses”; rate left blank. | Investigate coverage. Do not treat absence of replies as poor satisfaction. |
| Few responses or highly sensitive result | Count, rate where appropriate and “Limited evidence”. | Review individual themes; defer comparative rewards or penalties. |
| Selective invitations or inconsistent definitions | “Not comparable” with the reason. | Repair collection before interpreting differences. |
| Comparable collection with adequate evidence for the decision | Rate, base, period and uncertainty where justified. | Investigate differences alongside workload, customer mix and qualitative evidence. |
Avoid declaring that every result above a convenient count is reliable. A threshold can stop obviously fragile comparisons, but adequacy also depends on the effect you need to detect, the survey design and the consequence of being wrong. Agree the method with an analyst when decisions affect pay, contracts or substantial investment.
Also separate reliability from confidentiality. A group can have enough records for a useful operational summary yet still expose someone through filters or cross-tabulations. Disclosure controls require their own review.
Build an evidence strip beside each percentage
Numerator and denominator
Show positive responses and valid responses together. Define whether “positive” means selected answer categories, a rating threshold or something else. Exclude missing answers consistently and disclose exclusions.
Period and coverage
Show the collection window and, where available, valid responses divided by eligible invitations. Invitation coverage and response rate answer different questions; neither alone proves representativeness.
Comparison status
Use explicit text: “No responses”, “Limited evidence”, “Not comparable” or “Eligible for review”. Explain why. A green cell must not imply that the method has established a meaningful difference.
In Power BI, place these fields in the same table or matrix as the rate. Microsoft supports conditional formatting of values using rules and field values. Use it to reinforce the text status, rather than allowing a colour scale to turn every small difference into a performance judgement. [2]
Apply the evidence rule in the current filter context. A whole-company result may be usable while a sliced branch-and-service combination is not. Test exports and drillthrough pages too: the denominator and status must travel with the percentage.
Change the reporting window with care
Combining several months can give a small branch more evidence, but it changes the question. A rolling period describes a longer experience and can conceal a recent deterioration. Label its dates and keep the current-period count visible. Do not extend only the window for a branch whose result looks inconvenient.
Pool compatible records, not percentages. If one group has 4 positive responses from 5 and another has 60 from 100, their pooled rate is 64 ÷ 105 = 61.0% when rounded to one decimal place. The simple average of 80% and 60% is 70%, which answers a different question by giving the groups equal weight. This is an illustrative example, not a customer result.
Before pooling, check that questions, eligibility and response units match. If you intentionally weight branches equally, label that as an average branch rate. Survey weighting and repeated responses need a method suited to their design; raw pooling is not a universal substitute.
Replace automatic ranking with an accountable review
Collection owner
Standardise invitation rules, record the eligible population and monitor duplicate responses. Document channel changes so an apparent improvement is not simply a change in who was asked.
Analytical owner
Approve the denominator, grouping, weighting and comparison method. Where intervals are justified, document their assumptions. Do not use overlapping or non-overlapping intervals as a universal shortcut for every comparison.
Report owner
Maintain status logic, explanatory text and export behaviour. Test empty groups, tiny filtered groups and totals. Version policy changes so readers can understand why a status changed.
Decision owner
Agree which actions require stronger evidence and which can proceed through case review. Record the decision and follow-up question rather than asking teams to defend a position in an unstable ranking.
Trial the change in one management cycle
Start with one customer-feedback report. Review recent meeting notes to identify decisions based on ranks or coloured percentages. Add the evidence strip and replace the ranking with an alphabetical or operationally meaningful order where comparative evidence is weak.
Ask managers to interpret a small group, a no-response group and a large but selectively collected group. Have them explain what action is justified. If they still equate “eligible for review” with “proven better”, improve the label and meeting guidance before extending the design.
Track the share of displayed rates accompanied by their base, the share of filtered views with an appropriate status, and how often a decision is revised after someone discovers the denominator. Also track response coverage and unresolved collection issues. Set baselines before the change; do not claim savings merely because fewer branches are coloured red.
The intended business impact is better-targeted investigation, fairer comparison and fewer avoidable disputes. Judge the pilot by decision quality as well as dashboard adoption.
Assess your percentage reporting
Tick only controls you can demonstrate. This local assessment sends nothing and saves no responses. It evaluates reporting practice, not statistical significance.
Frequently asked questions
Is there a universal minimum sample size?
No. The required evidence depends on the decision, sampling design, variability and acceptable uncertainty. A display threshold is a reporting policy, not proof of statistical reliability.
Does a larger response count remove bias?
No. More responses can reduce sampling variability under suitable assumptions, but they do not automatically correct selective responses, duplicate submissions or a poorly defined population.
Should a small group disappear from the dashboard?
Not automatically. Show its count and a clear comparison status where appropriate. Apply separate disclosure controls when the information could identify individuals.
Can we average team percentages to get the business result?
Usually not. For a pooled unweighted response rate, divide the combined positive responses by the combined valid responses, provided the groups and definitions are compatible.
Give every percentage the context it needs
Smart Statistics can help review your Power BI measures, expose weak comparisons and design reporting that supports clear, proportionate decisions.